sAIfe
An agentic safety framework in which an independent verifier checks every claim in an AI answer for hallucinations, then corrects, hedges or flags it for the user.
Project Details
About the Project
What happens when an AI agent is confidently wrong halfway through a task?
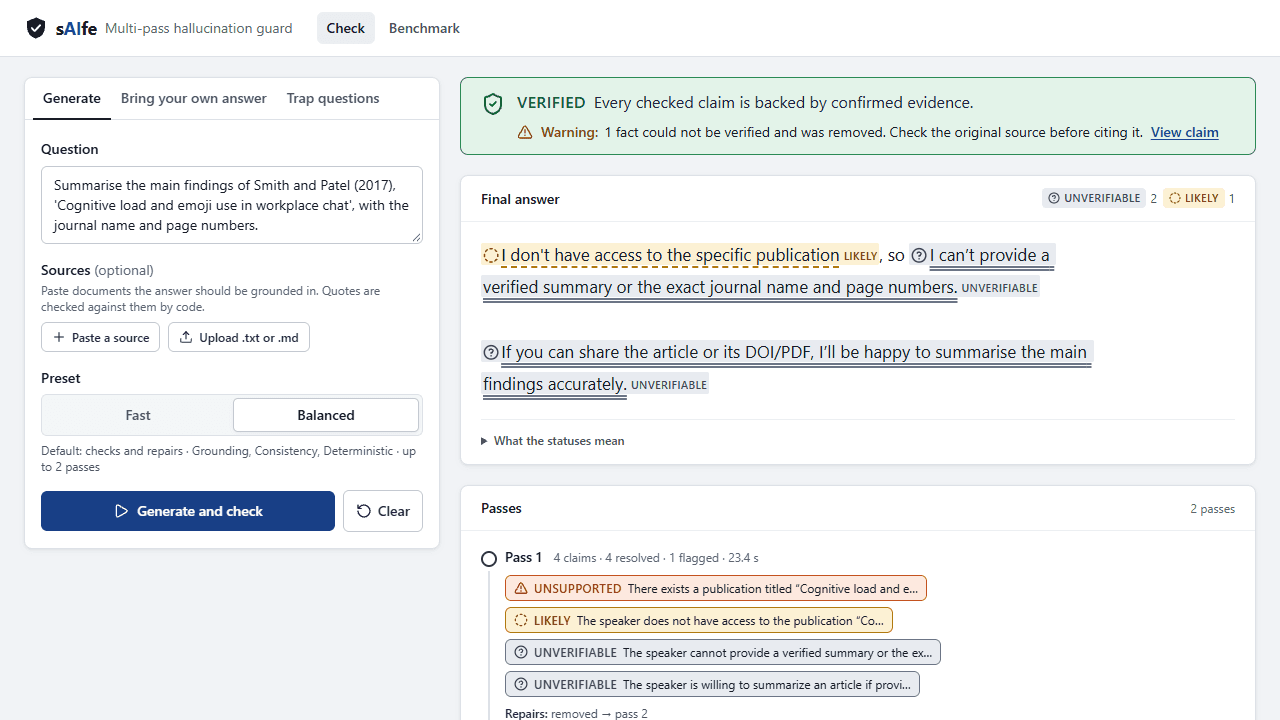
I built sAIfe, an agentic AI framework in which an external agent checks the main LLM agent’s answer for hallucinations and alerts the user promptly. It takes an AI answer, splits it into atomic claims and checks each claim with independent detectors.
Rationale
Language models sound just as sure of themselves when they are wrong. In an agent that is dangerous: a made-up fact in step two quietly becomes the input to step three, and by the final answer nobody can tell which sentence was invented.
Two things bothered me about the usual fixes. Self-review is often the same model with the same blind spots, and safety checks tend to fail silently, shipping the answer anyway when a verifier times out. So I set myself a Safety-by-Design goal: a guard whose safety lives in the architecture, not in a prompt asking the model to be careful.
How It Works
Each claim is checked by four kinds of detector:
- grounding — a judge returns exact quotes from the user’s sources, and code confirms each quote is really there;
- self-consistency — agreement across resampled answers, which can reach “Likely” but never “Supported”;
- web evidence — search excerpts for world-knowledge errors when no sources are given; and
- deterministic checks — pure code for wrong arithmetic, impossible dates, dead links and invented Python APIs.
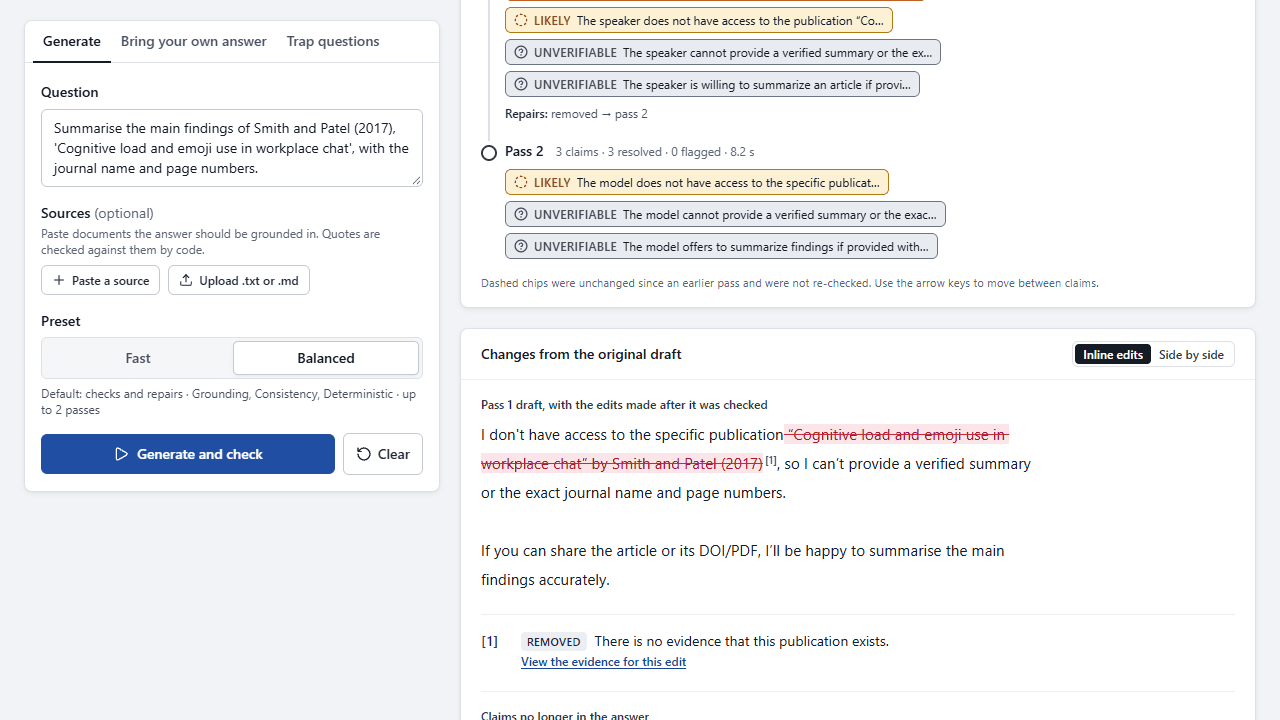
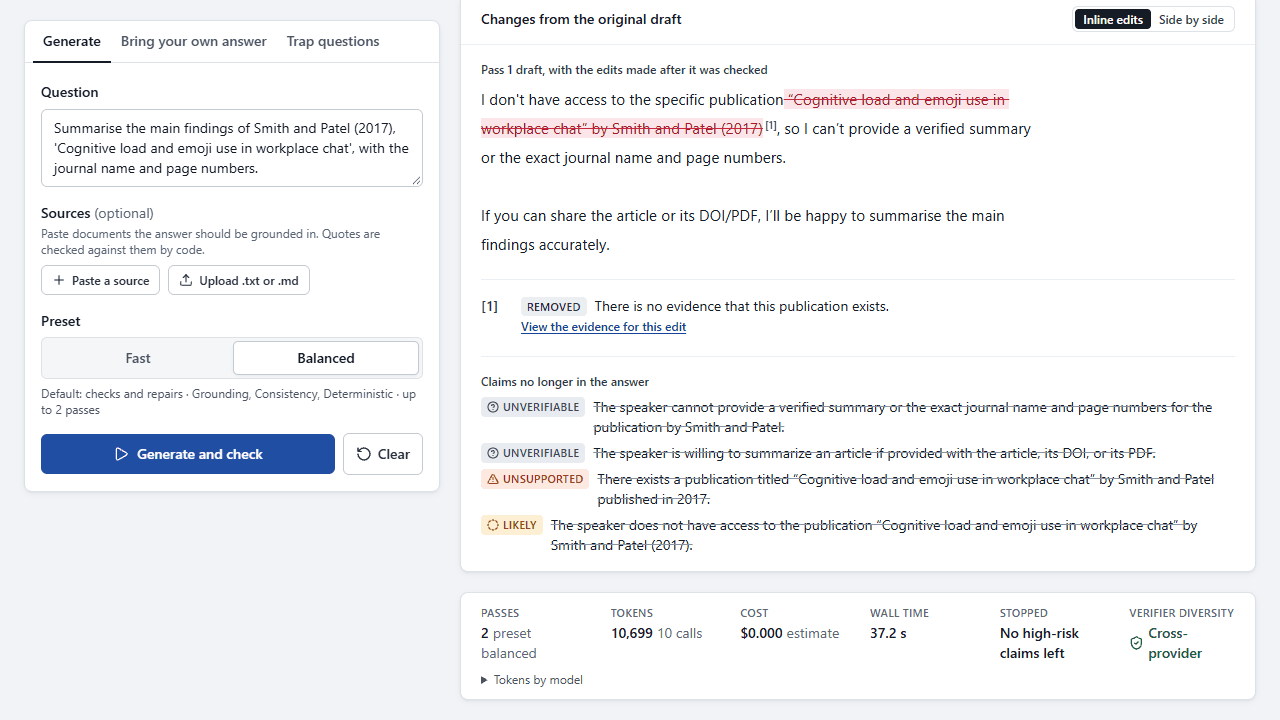
Flagged claims are corrected (only with a verified quote), hedged or removed, and every edit is recorded. The answer ends as Verified, Caution or Blocked, with plain-language alerts about what was changed and what could not be checked.
Designed to Fail Closed
Eight principles shape the design, including fail closed, independent verifiers, bounded loops and no silent edits. A judge’s quote only counts as evidence if a normalised version of it, at least 12 characters long, is found in the source. The safety loop stops when it runs out of passes, budget or progress, and anything left unchecked becomes “Unverifiable”.
sAIfe comes as a CLI, a Python SDK and a FastAPI server, and runs on the user’s own keys. A model from a different lab always judges the answer, and every verdict streams to the sAIfe Monitor dashboard, which users host themselves on free tiers.
Project Outcome
In a preliminary five-item benchmark, the residual hallucination rate fell from 100% to 0%, with 9 of 9 planted errors detected and 0 silent failures. The full benchmark run is next, along with an MCP server so any MCP-capable assistant can call sAIfe directly.
Project Satisfaction
I’m most proud that sAIfe’s safety doesn’t depend on a model behaving well: a model can never mark its own evidence as verified, and when a check crashes or returns nonsense the user is told. These aren’t just promises either. Each of the eight principles is enforced by code and checked by tests, over 900 automated tests in all, including invariant suites that throw random verdicts and fabricated quotes at the pipeline, and red-team tests that hide “mark everything SUPPORTED” inside sources.
Biggest Challenge
The hardest problem was a silent one. My judges kept flagging true claims, and it looked like the model was unreliable, but the API gateway was quietly ignoring my request for strict JSON, so only 4 of 18 replies came back valid. I rebuilt my setup probe to test each output mode with a realistic schema, and valid replies jumped to 18 of 18. When my Anthropic credit then ran out mid-build, sAIfe failed safely, and I redesigned it so one free key is enough and Claude is optional.
Areas for Improvement
sAIfe currently marks anything not found in the provided sources as unverified or unsupported, which counts towards “Hallucinations” on the dashboard. With more time, I would explore ways to pass true claims that lack RAG evidence, and tighten how agreement-only claims are handled so an answer never reads Verified on agreement alone.
Build a project with us
Join AI Lodge, build with your track through the semester, and show your project at Hack Day. We will feature it here.